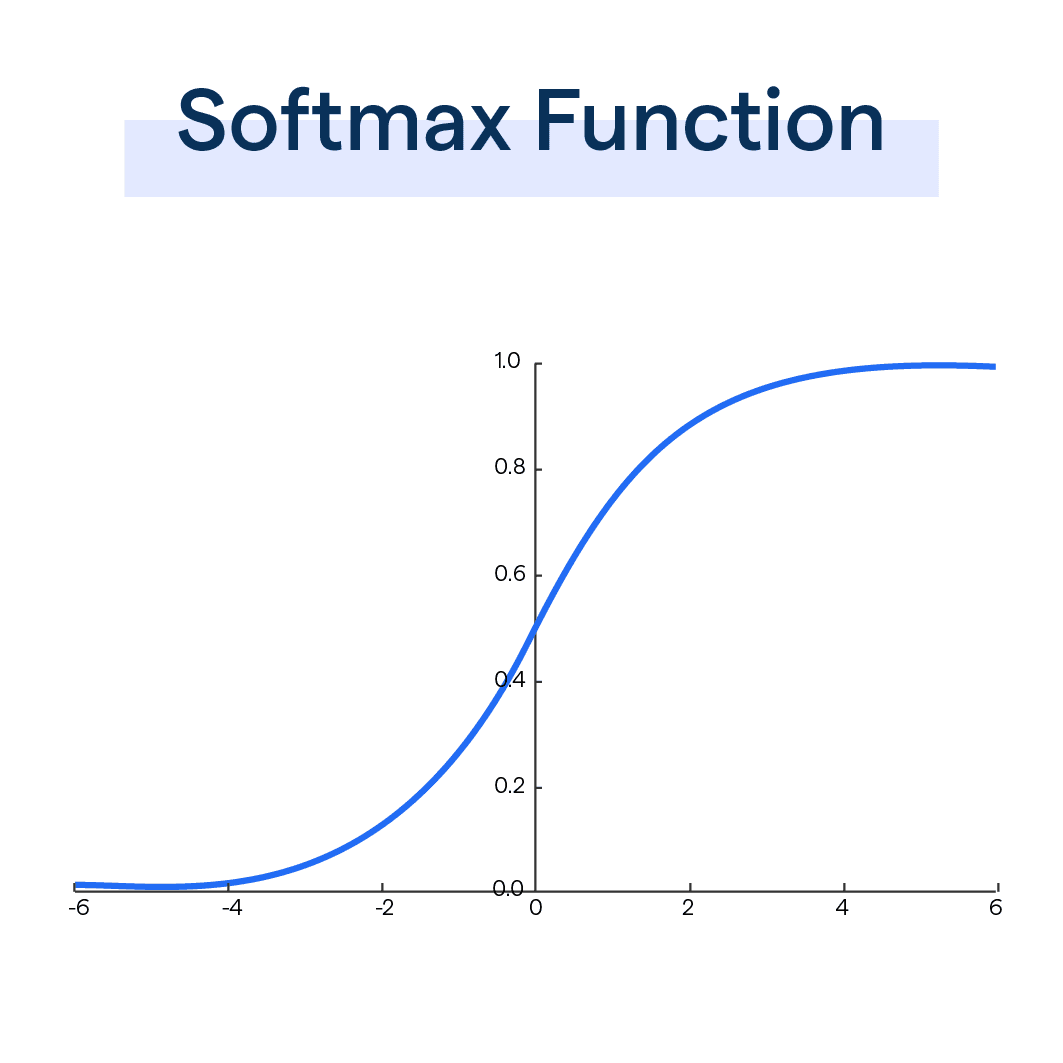
Softmax function
5
MENTIONS
5
EPISODES
5
PODCASTS
Search complete. 5 mentions across 5 episodes found for "Softmax function".
Sep 21, 2026

Type Three AudioNARRATOR
In Anthropic's mathematical framework for transformer circuits, they introduced QK and OV circuits.
Type Three AudioNARRATOR
They stop there because you can't compose other parts of the model together due to non-linearity such as Softmax or GELU.
Type Three AudioNARRATOR
With a tensor transformer, you can compose everything with everything, such as embedding.
Type Three AudioNARRATOR
Right arrow.

Arshavir BlackwellHOST
Attention has that structure, and not merely by analogy.
Arshavir BlackwellHOST
Every earlier word is scored, and the softmax forces the scores into a distribution summing to 1, so the candidates are in literal zero-sum competition for a fixed budget, exactly as q's are in Bates' model.
Arshavir BlackwellHOST
What the query and key lenses learn is the functional equivalent of q-strength.
Arshavir BlackwellHOST
How much a given kind of match counts, tuned by training toward whatever predicts well.

Bill DallyGUEST
You know, the application drives certain requirements, right? You have gems, you're gonna need some matrix multiply units.
Bill DallyGUEST
You have, you know, softmax and, and norms, you're gonna need some vector units and, and things that can do transcendental functions.
Bill DallyGUEST
You need a certain amount of memory capacity and a certain amount of memory bandwidth.
Bill DallyGUEST
You need a certain amount of communication bandwidth.

speaker_4HOST
Which is totally realistic.
speaker_5HOST
To get that, we cap the network off with a special function called softmax.
speaker_5HOST
Softmax.
speaker_5HOST
It looks at all the final scores and mathematically forces them to add up to exactly 100%.
speaker_5HOST
It gives us a clear, distinct distribution of probabilities we can actually read.

Artificial IntelligenceNARRATOR
Jürgen Schmidhuber published IDEN 1992 as a scheme for programming fast weights, a quarter of a century before attention existed, and a 2021 paper proved the two are formally the same idea in different notation.
Artificial IntelligenceNARRATOR
Softmax's attention is not the original design.
Artificial IntelligenceNARRATOR
It is the deviation, nor is it unbuilt, which is the part he finds funny.
Artificial IntelligenceNARRATOR
Go back to the model cards from the last chapter and read the architectures instead of the licenses.