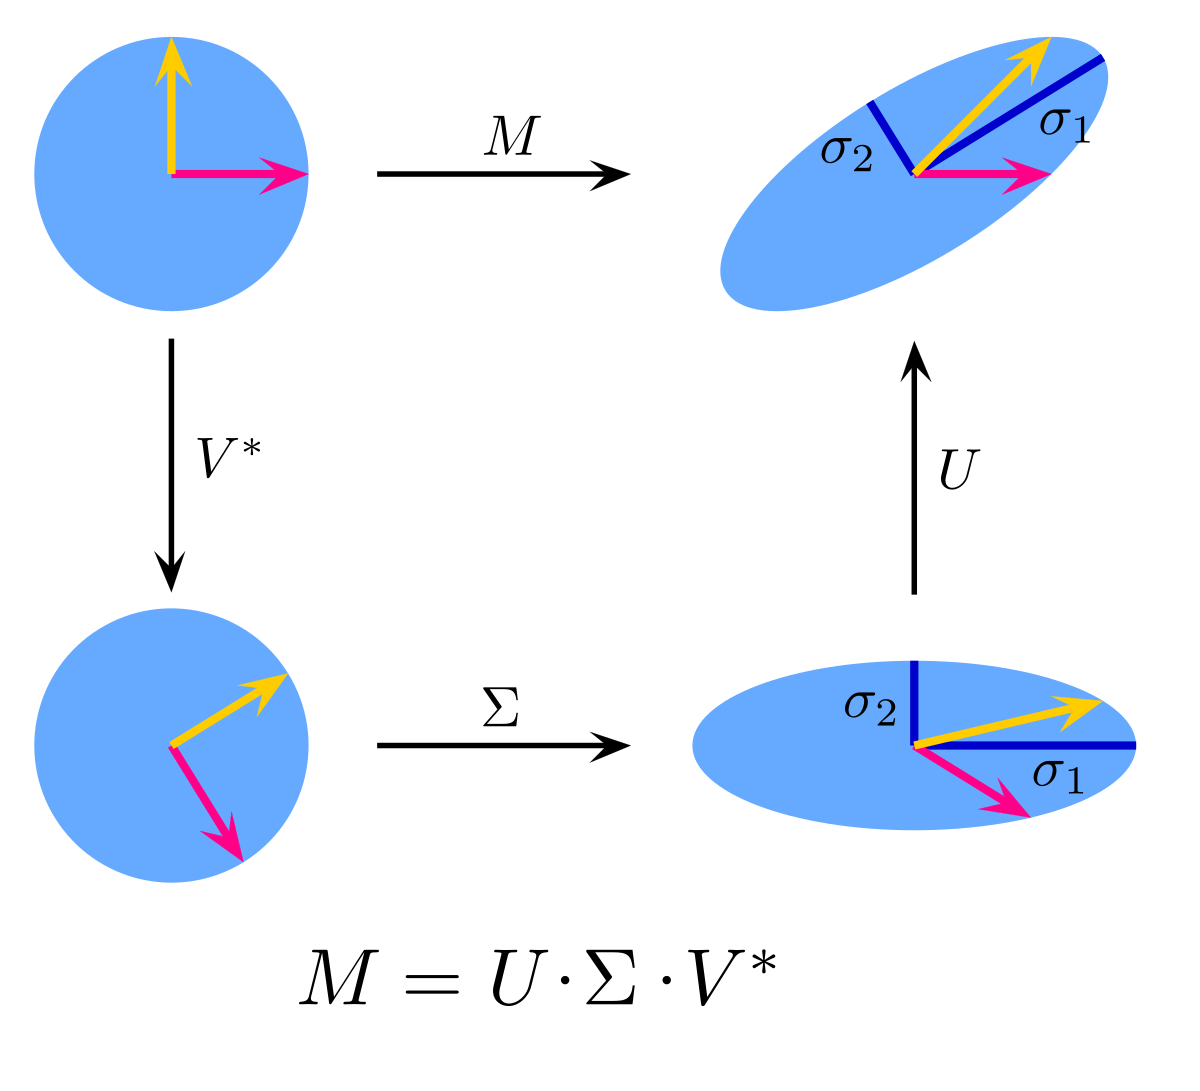
Singular value decomposition
11
MENTIONS
5
EPISODES
2
PODCASTS
Search complete. 11 mentions across 5 episodes found for "Singular value decomposition".
Nov 1, 2026

Christopher PottsHOST
We're gonna start with the classic, which is a matrix factorization method called latent semantic analysis.
Christopher PottsHOST
It's also called truncated SVD for singular value decomposition.
Christopher PottsHOST
That's really the underlying algorithm.
Christopher PottsHOST
This is one of the oldest and most widely used reduction techniques.
8 MINS LATER
Christopher PottsHOST
They're slightly differently scaled and they're different values, um, but it's kind of more tractable looking.
Christopher PottsHOST
One more note about this.
Christopher PottsHOST
So when you read about truncated SVD or LSA, uh, the, the question comes up of how you would pick the dimensionality K in the sense of like I picked two here.
Christopher PottsHOST
But you're working with matrices that have 5,000 dimensions.
Tengyu MaHOST
Transpose, and then you get U times I minus eta sigma square U transpose.
Tengyu MaHOST
And this is the SVD for,
speaker_4UNKNOWN
or
Tengyu MaHOST
the
speaker_4UNKNOWN
eigen decomposition of
Tengyu MaHOST
SVD for I minus eta phi phi transpose.
Tengyu MaHOST
And that's why what's inside is the eigenvalues or the singular values for the resulting matrix.
Tengyu MaHOST
And then now you bound this.
Tengyu MaHOST
Even that's not trivial.
Tengyu MaHOST
So for matrices, it's trivial because you just take SVD.
Tengyu MaHOST
But for tensors, it's not trivial.
Tengyu MaHOST
So that's why the first is to say, I get an exact low rank tensor.

Type 3 AudioNARRATOR
When the prediction maps are linear, the update maps are linear plus normalization, and there are no non-negativity constraints, the GBS representation is called a generalized HMM.
Type 3 AudioNARRATOR
A minimal GHMM with the smallest dimension can be identified by SVD of the Hankel matrix.
Type 3 AudioNARRATOR
Subheading.
Type 3 AudioNARRATOR
3.3.
Type 3 AudioNARRATOR
Example.
Type 3 AudioNARRATOR
We now illustrate GBSs on the Merksa example.
Type 3 AudioNARRATOR
First, we compute a minimal GHMM using the SVD algorithm.
Type 3 AudioNARRATOR
For the Merksa process, it is five-dimensional.
Percy LiangHOST
Yeah.
Percy LiangHOST
The question was, is SVD fast on GPUs? SVD is not fast on GPUs, but they're not doing SVD.
Percy LiangHOST
What they're doing is Newton-Scholz.
Percy LiangHOST
Newton-Scholz is a matrix multiply only finite iteration algorithm that approximates the process of orthogonalizing a matrix.