Markov chain Monte Carlo
142
MENTIONS
35
EPISODES
8
PODCASTS
Search complete. 142 mentions across 35 episodes found for "Markov chain Monte Carlo".
Nov 20, 2026
Michael JordanGUEST
So that's a Bayesian version of a mixture model, a finite mixture model written as a random measure.
Michael JordanGUEST
Okay, and let's, since I'm not spending a lot of time on the statistics here, let's just wave our hands and say we can do Bayesian inference with MCMC or the Gibbs sample or the glabrodynamics, whatever you want.
Michael JordanGUEST
Just take that kind of graph, take one node at a time, and sample from conditional probabilities associated with it, and it'll converge and so on and so forth.
Michael JordanGUEST
All right, so now let's go on to the harder problem, which is how do we pick K? How do we know, we don't know the number of clusters a priori, how do we handle that? And so now we're gonna try to return to this idea of the Chinese restaurant, now from a more sophisticated perspective.
13 MINS LATER
Michael JordanGUEST
One is a little bit about how you do inference with these things, and then how you can use it for various kinds of interesting applications.
Michael JordanGUEST
So the first one is how do you do inference? And we've already kind of waved my hands at explaining this.
Michael JordanGUEST
You can do MCMC with this kind of model.
Michael JordanGUEST
So this is now an infinite object.
David BleiGUEST
That's how I analyze this data Sam
SamUNKNOWN
Just a sort of general question Both the variational methods in the MCMC methods because they never really mix have the property that they sort of find one mode one plausible Posterior mode.
SamUNKNOWN
Yeah approximated and their strength comes from the fact that not only can get a sort of point estimate But you get some indication of the volume of the mode that allows you to do sensible Calculation Yeah, but From a statistician's point of view, these things that you're estimating are really nuisance parameters.
SamUNKNOWN
And if I run it once, and I get some set of topics, and I run it again, and I get a different set of topics, that's OK.
13 MINS LATER
David BleiGUEST
So let me just talk a little bit about what variational inference is quickly so you know and might want to learn about it.
David BleiGUEST
OK, so forgetting everything, what we're after is a distribution of these hidden variables given our observations.
David BleiGUEST
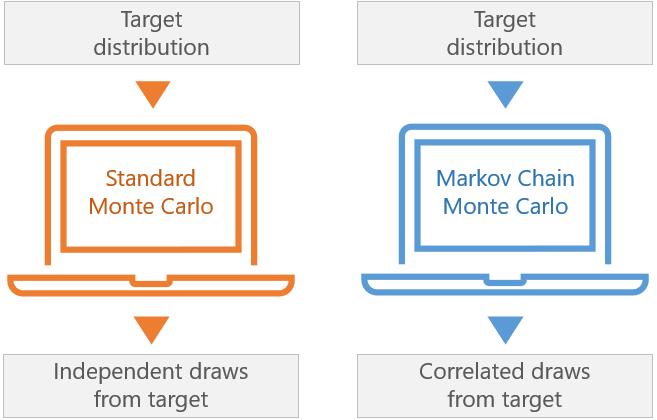
And what things like Gibbs sampling and MCMC that we've mentioned a few times today do are define Markov chains on those hidden variables such that the limiting distribution of those chains is the distribution we care about.
David BleiGUEST
And then you approximate the distribution you care about by looking at empirical distribution of samples from that chain.

speaker_0HOST
very happy to have charlotte to join this august seminar she is currently a postdoctoral researcher at brown university working under supervision of professor eli apfel charlotte's expertise is to employ combinatorial structures and statistical tools to model massive data problems Her area of research includes study of social issues in online networks, analysis of algorithms using MCMC, and study of primary problems in graph mining in different computational models.
speaker_0HOST
She received her PhD from Dartmouth College, where she was working under the supervision of Professor Peter Winkler.
speaker_0HOST
Today, she's going to talk about reducing polarization and increasing diverse navigability in graphs by inserting edges and swapping edge weights.

Ruijie HeHOST
While we're challenging the distribution assumptions, I mean, should we be going even broader to challenge the Gaussian assumption, that kind of distribution assumption? For instance, if you do a just pure sort of...
Ruijie HeHOST
MCMC kind of approach, do you get a completely different type of distribution? And then you realize that the Gaussian assumption is even that Dow curve distribution is completely broken.
Jiayuan MaoGUEST
I think that's definitely right.
Jiayuan MaoGUEST
I don't think the, you know, the particular distribution that we choose, you know, at the end, you know, at the end of this paper is the optimal one or is like the really, you know, the broadly applicable one.
Alan ChristopherGUEST
If they don't, I carry on to the next iteration.
Alan ChristopherGUEST
And not having to do any fancy Monte Carlo Markov chain stuff, trying to make sure that I'm sampling from the cluster, this is just plain frequentist observation that Long-term rate of an event is its probability.
Alan ChristopherGUEST
Return hits over trials, bang, we have a result.
Alan ChristopherGUEST
And we've made no simplifying assumptions.

speaker_14AUDIENCE
Thank you so much.
speaker_9AUDIENCE
Out of curiosity, have you tried the opposite approach of quality first and diversity afterwards? to see if, because you said first we go for sort of like Monte Carlo Markov chain, you're doing exploration, exploitation kind of thing.
speaker_9AUDIENCE
And you got better results by doing diversity first and quality after?
Shrimai PrabhumoyeGUEST
Yeah, so in the two-phase approach, yeah, we first wanted to do diversity and then quality, and then we did have an ablation where we swapped that and it didn't give as good results, yeah.
Yoshua BengioGUEST
But there's a reason why this is happening, and I'm going to try to explain it to the picture.
Yoshua BengioGUEST
So first of all, as I mentioned, MCMC methods move in configuration space by making small steps.
Yoshua BengioGUEST
You start from the configuration of the examples.
Yoshua BengioGUEST
Let's say where I'm sitting is a configuration of x, y coordinates.
Yoshua BengioGUEST
It's a region that has a peak.
Yoshua BengioGUEST
And this is another mode, so this distribution has two modes.
Yoshua BengioGUEST
The question is, can we go from mode to mode and make sure to visit all the modes? And the MCMC is making small steps.
Yoshua BengioGUEST
Now, so long as the MCMC can go through these intermediate regions and they have enough probability, it can move around here and then quickly go through these and do a lot of steps here and go back and in this way assemble all the configurations with roughly the right probability.

Alex AndorraHOST
So in Python, that way you have VRMS, you have Python, you can choose whatever you prefer.
Alex AndorraHOST
and uh and you can see the effect of the priors i see actually i show actually different different priors and and i show that actually having a white prior doesn't mean it's a good prior um so yeah to to echo exactly what you said um and now it's so much easier to to start with these tools, not only because we have supercomputers in our hands, and our personal computers now are so powerful, and thanks to open source software like BRMS and PyMC, we can actually sample MCMC in a matter of seconds.
Alex AndorraHOST
So that's definitely a game changer.
Alex AndorraHOST
And also now you can get some assistance if you do it well from AI agents.

Roy LedermanGUEST
And there are all these methods that people came up with to make this cheaper, right? I mean, we don't actually look at all these different orientations.
Roy LedermanGUEST
But it starts to be a question of, to what extent can you still do this when you have these sort of flexible models and people can do weird things with them? So how much can you predict what people would do and predict how you want to do this? So directions we're looking at for several reasons is Markov chain Monte Carlo.
Roy LedermanGUEST
So what Monte Carlo does where it works well is you have your posterior distribution, and you try to sample from that posterior distribution.
Roy LedermanGUEST
In our case, it means sampling these hypervolumes, describing an object with all of its heterogeneity.
25 more episodes mention Markov chain Monte Carlo.
Create an account to see the whole feed, search across every transcript, and follow the entities you care about.