F-score
19
MENTIONS
8
EPISODES
7
PODCASTS
Search complete. 19 mentions across 8 episodes found for "F-score".
Oct 23, 2026

Junaid KaliaHOST
For that, we have to use dice.
Junaid KaliaHOST
For our medical coding, which is essentially being able to understand that the prediction that the AI produce, how much it is, then we use F1 score.
Junaid KaliaHOST
If you are actually going through these back office operations, et cetera, and for example, there's a prior authorization call that my voice agent does, then for that is task completion rate.
Junaid KaliaHOST
not full task completion rate, not the small bits of, because every task is every job.
Junaid KaliaHOST
So one of the things that we have done consistently in our work is that we have what we call a golden data set.
Junaid KaliaHOST
That golden data set essentially is our hard-coded physician verified, multiple clinician verified, and we can quickly check that, okay, this is the ground truth.
Junaid KaliaHOST
Then once you have the ground truth for different applications for different KPIs, then you assess that back and say, okay, the new model or the new variation of the new model or a completely new engine like decision engine comes in, then you adjust the F1 scores and then depending on if the results are good, then you update
Harvey CastroHOST
it.

Aleksandra ZurawHOST
Apreedia, Booth 301, Pathology Visions 2026.
Aleksandra ZurawHOST
[percussive music] This is F1 score, and, uh, here is accuracy, and this is how much it lost.
Aleksandra ZurawHOST
So VirCo, as you see on the chart here, stays more or less at the bottom, so it loses the least.
Aleksandra ZurawHOST
But scanner held out f- F1 was down 13.6 to 19.5%.
Aleksandra ZurawHOST
And center held out, F1 was down from 6.9 to 14%.
Aleksandra ZurawHOST
Circle size is the parameter count, so PathGiga is bigger than Virko2 and less stable, but it lost more, right? When you look at this, this is how much it lost, whereas our Virko lost less.
Aleksandra ZurawHOST
So that's what happened unfortunately.
Aleksandra ZurawHOST
And yeah, the, the metric that...

Volodymyr HreskoGUEST
So it's getting better super fast.
Volodymyr HreskoGUEST
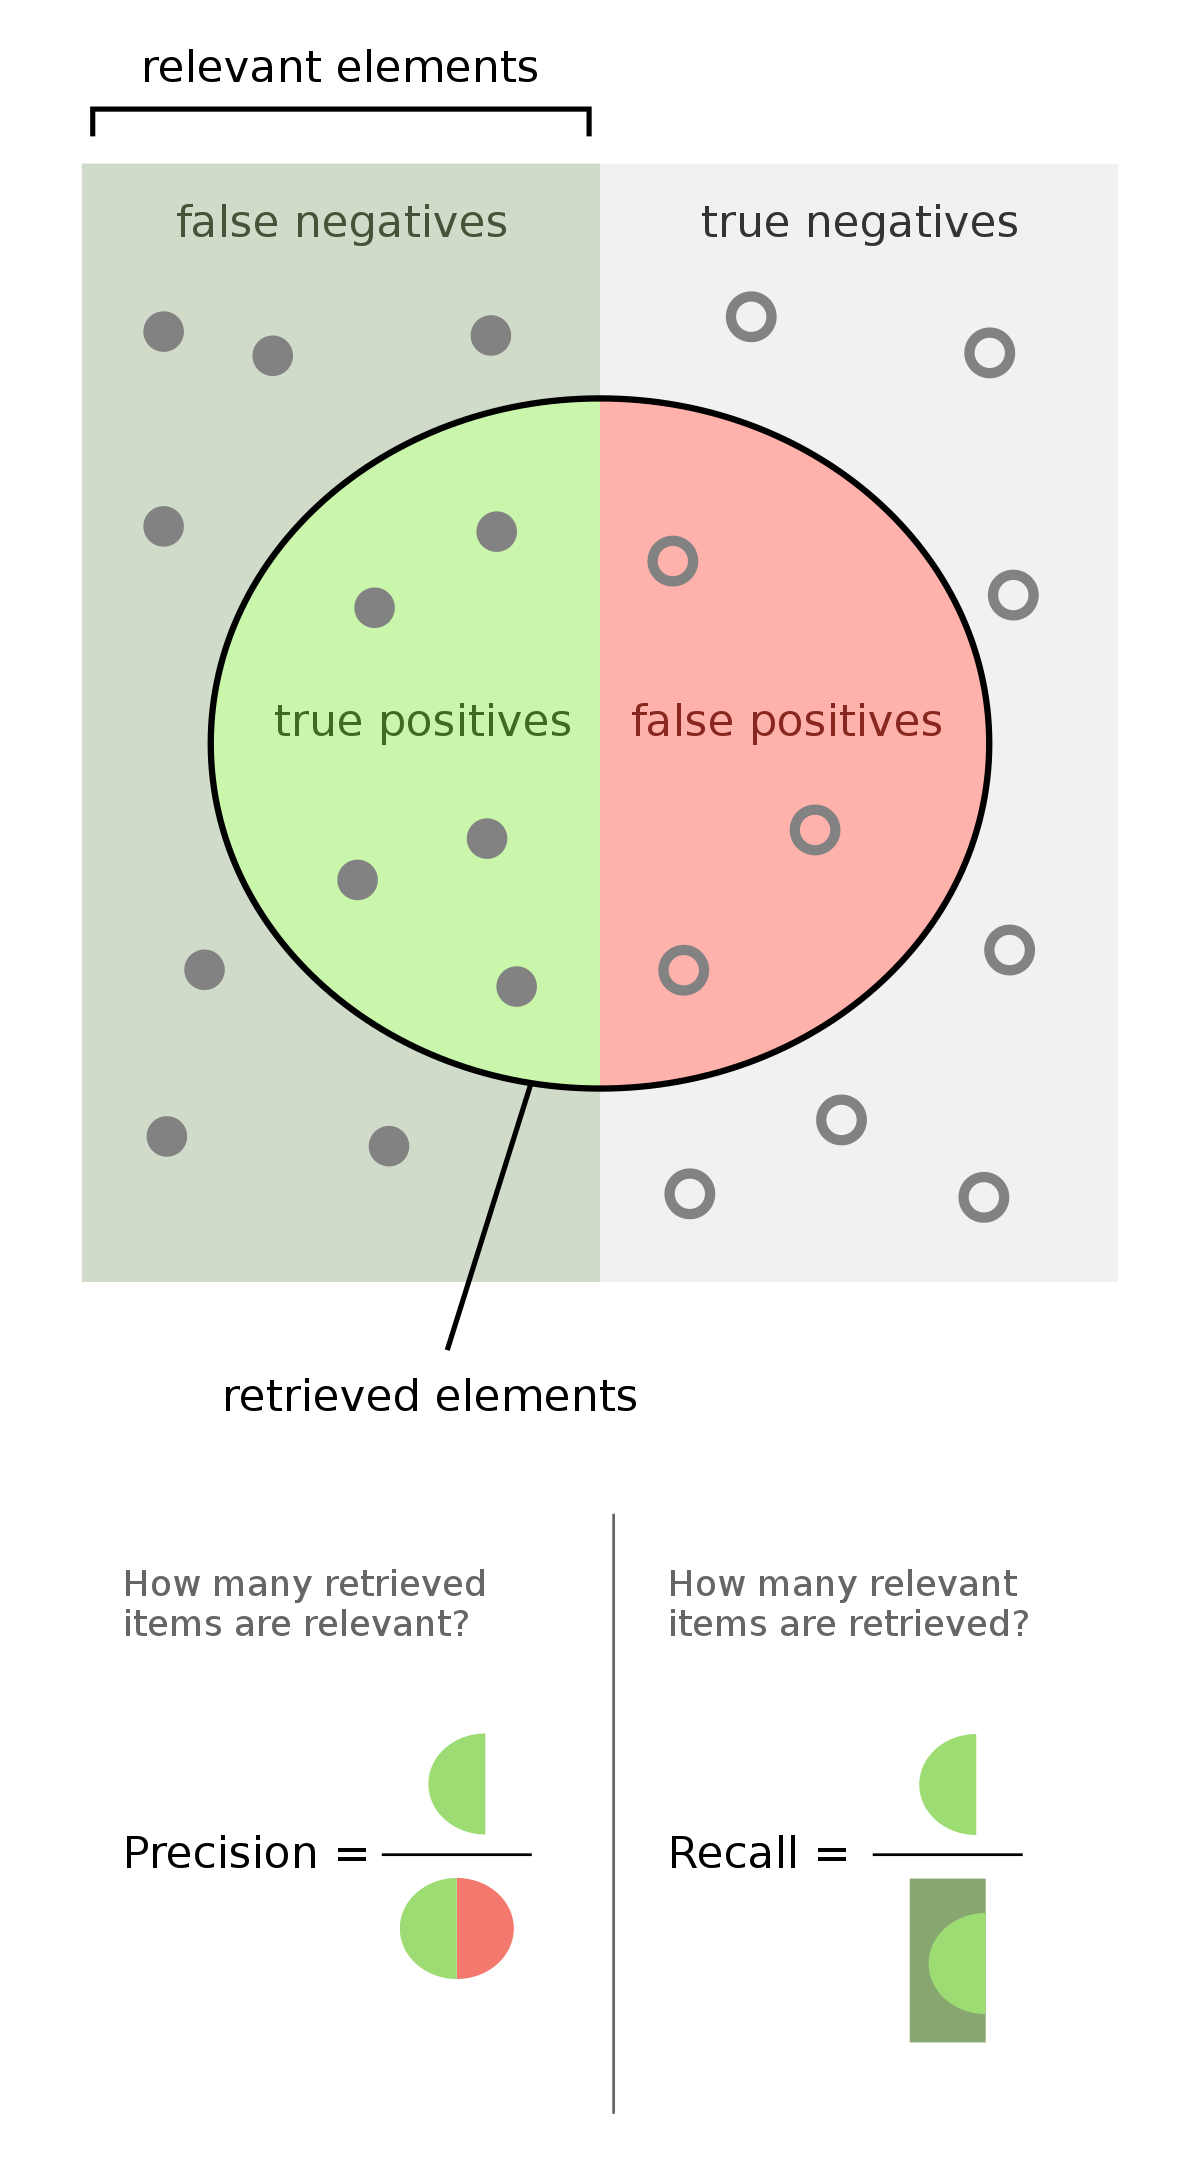
Like just a month ago, what we actually measure, just to take a step back, is a score, the name is F1, which actually tells us not just how accurate is it, but also how trustworthy is it.
Volodymyr HreskoGUEST
Because it looks not only for the found objects, but also for objects that are not supposed to be found.
Volodymyr HreskoGUEST
Because for example, if an AI is looking at the drawing.

Tonghe ZhangGUEST
So the agent starts the auto research to synthesize a function, actually a series of functions, to tell if the strap is passing through the head and how long does it pass through, and is this really intersecting with the head or it's, it's actually not.
Tonghe ZhangGUEST
So eventually the agent is able to hit 80 to 90% F1 score on the offline success or failure binary dataset that I provided, and it also knows how to accelerate this process to make the reward function very, very fast.
Tonghe ZhangGUEST
It, it, it reduced the time to tell from one second down to 100 milliseconds so that this reward system becomes real time and also mostly reliable.
Tonghe ZhangGUEST
Yeah, that's how we develop this reward function.
Wenli XiaoGUEST
Go ahead.
Michael ChoHOST
Yeah.
Michael ChoHOST
Actually, Tonghe, I'm curious, like, uh, you know, it took you three days, you know, original human effort, you, you gave up, you do this auto research thing, and then, you know, I, I guess the agent figures something out, very good F- F1 score.
Michael ChoHOST
So, uh, but eventually, like, uh, when you look at the actual reward function done by this agent, like, it's, is it humanly like, uh, do, do

David TalbyGUEST
Is it better, right? Which is a very hard question.
David TalbyGUEST
It's not an F1 to come and say, oh, do you identify more cats in this picture? It's more, okay, this is such a broad thing, which is how do you even test it? The second piece is really also is it safe, okay? So as a CEO would ask, you know, will this get me on CNN? Am I not going to find out, right? That, oh, I stopped hiring women, right? Or I stopped giving loans to Jews now for some reason, right? Or I, you know, launched profanities and some of my, you know, customer service calls at some of my customers, right? No.
David TalbyGUEST
Exactly.
David TalbyGUEST
Or, you know, you could be a medical procedure.