Diffusion model
14
MENTIONS
3
EPISODES
3
PODCASTS
Search complete. 14 mentions across 3 episodes found for "Diffusion model".
Sep 8, 2026

speaker_1NARRATOR
Speaking of discovery, let's talk about the technical side.
speaker_1NARRATOR
How does Emot explain diffusion models versus the standard transformers?
speaker_0NARRATOR
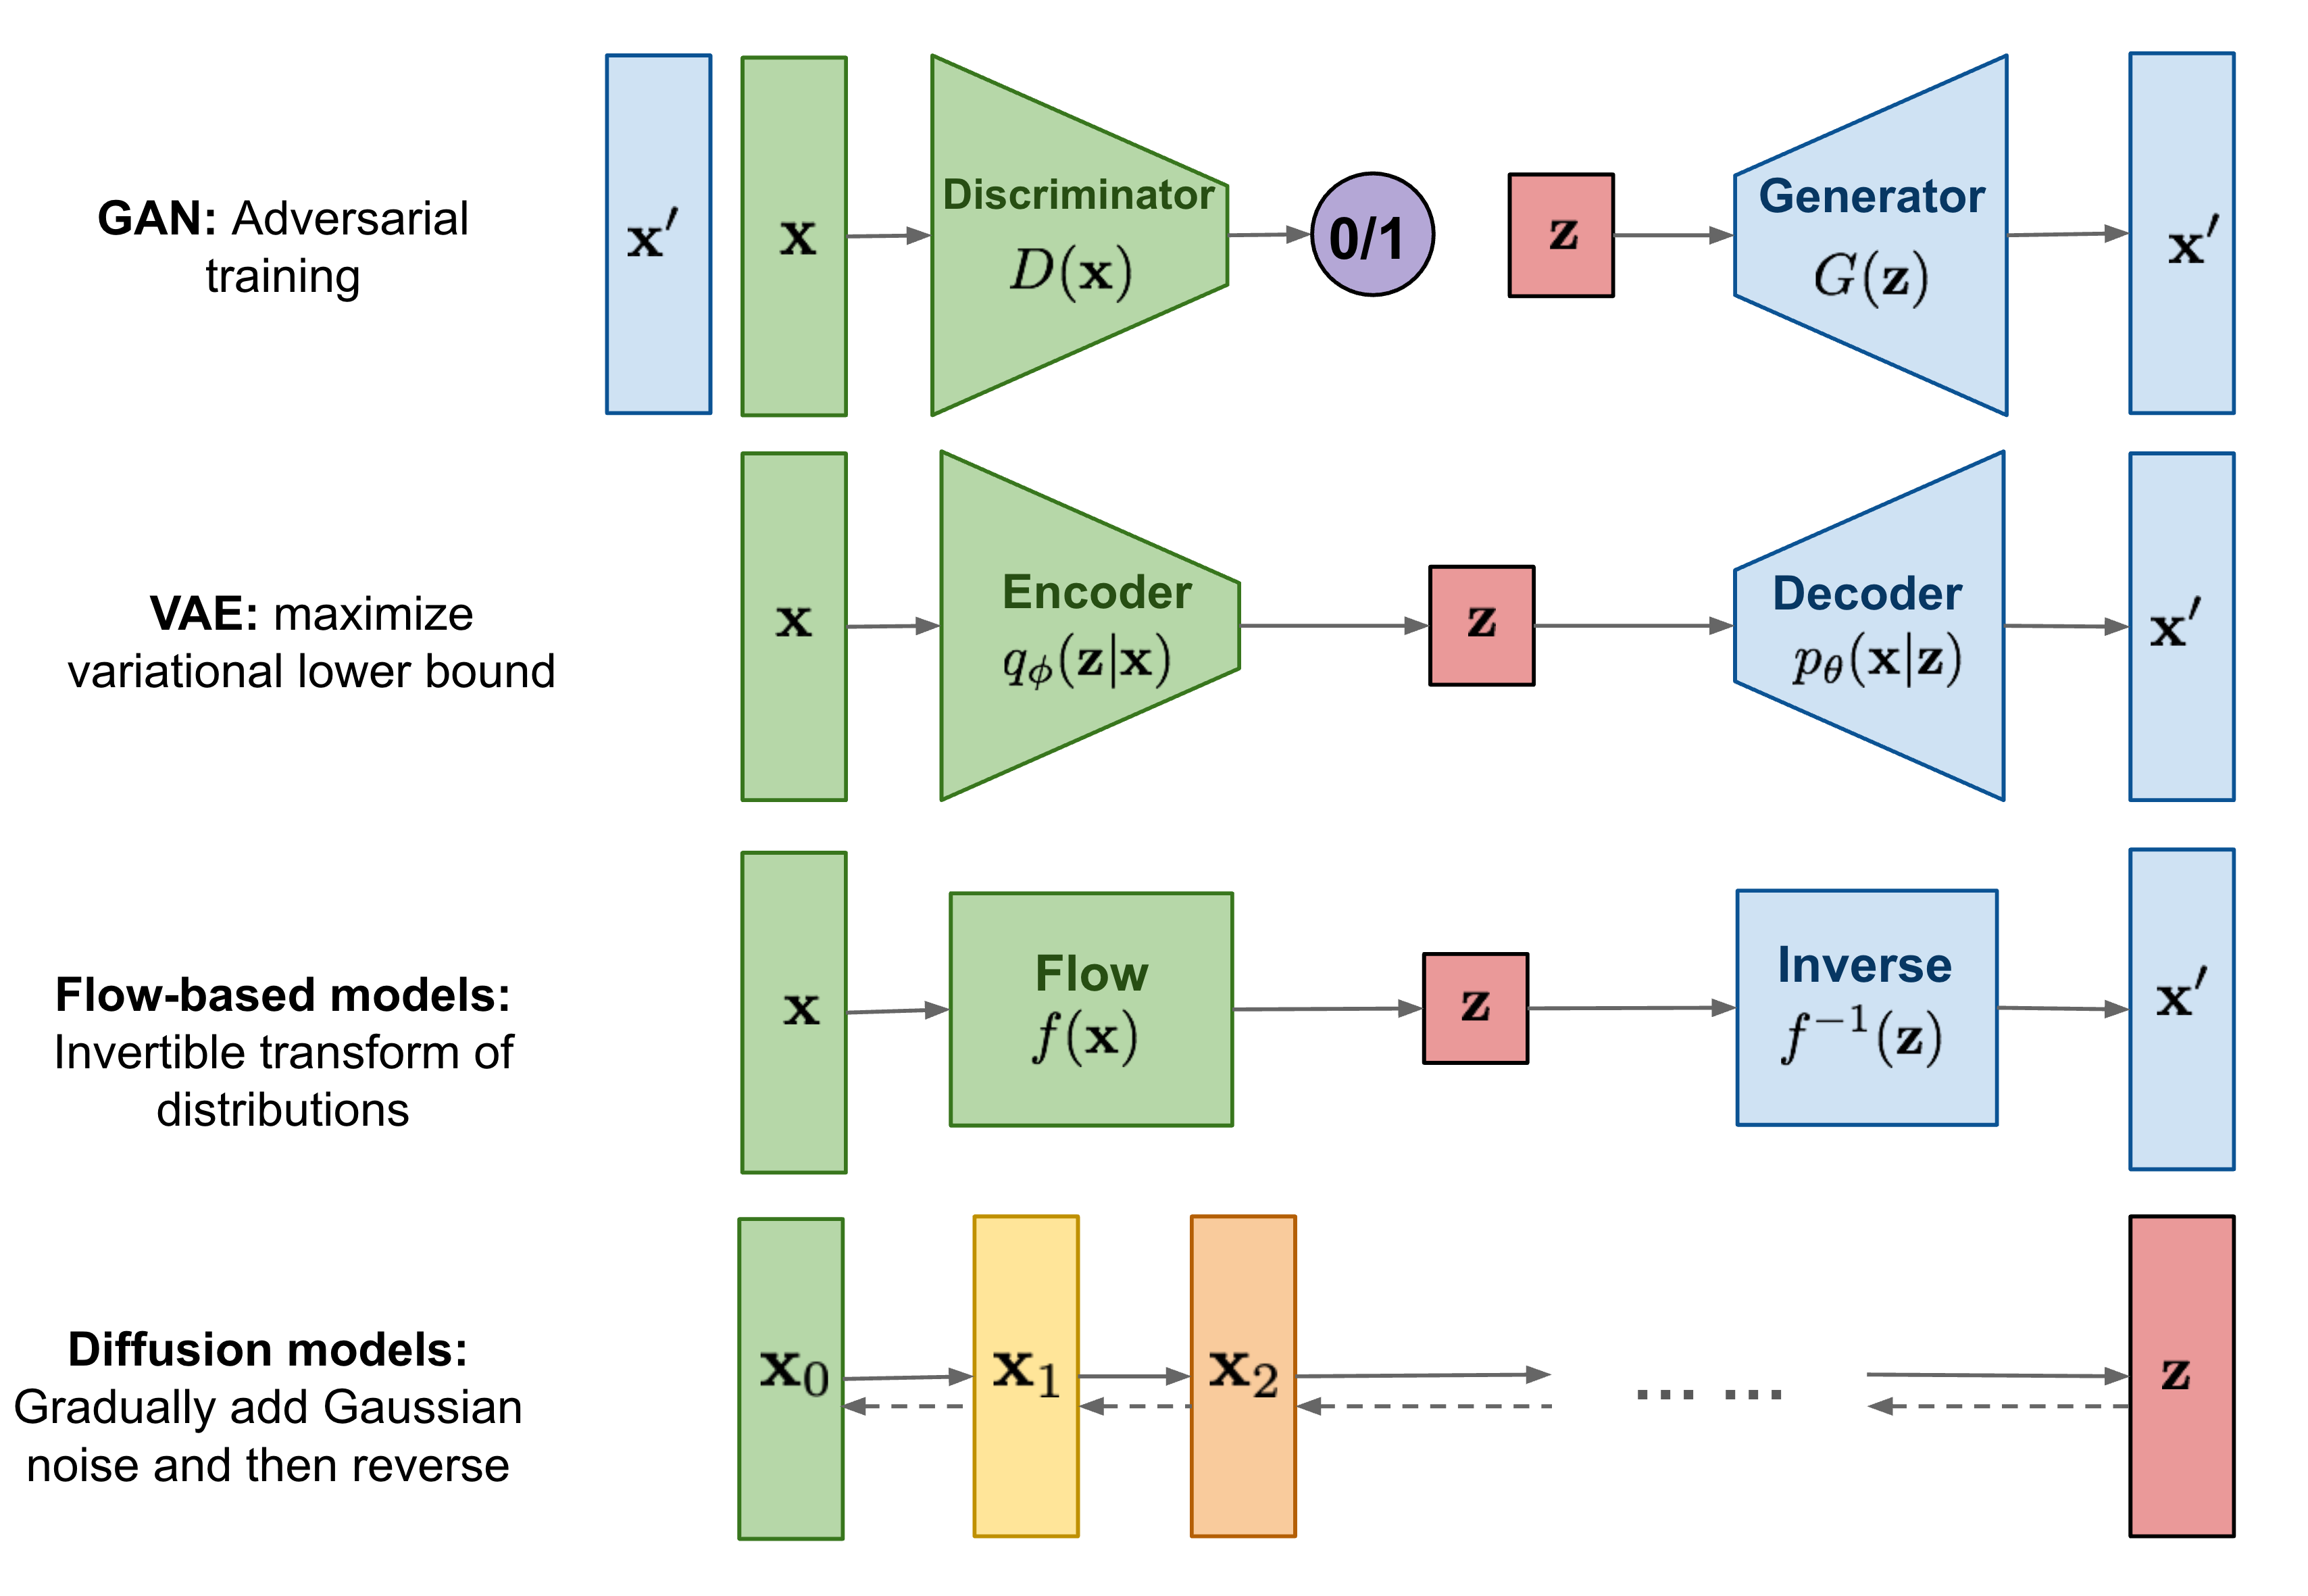
He contrasts autoregressive transformers with diffusion models by explaining that diffusion works by destroying data with noise, then learning to reconstruct it.
speaker_0NARRATOR
He sees that process as tied to compression, least action, and even how nature itself seems to minimize effort while preserving structure.
speaker_1NARRATOR
And stable diffusion itself was meant to democratize this technology, right? Exactly.

speaker_1ADVERTISER
Fresh for everyone.
Dagogo AltraideHOST
DALI2 actually generates the image using a process called diffusion, which has been described by the company as starting with a bag of dots and then filling in a pattern with greater and greater detail.
Dagogo AltraideHOST
Diffusion is the hottest new method of AI generation and can be a whole other topic for another day.
Dagogo AltraideHOST
But in order to save time, let's move on to something that I find a lot more interesting.
Dagogo AltraideHOST
The mimicking of human preference.